TRABSA: a mental-health statement classifier
Why
Custom architectures get published without anyone checking whether a plain baseline would have done the same job. I wanted the comparison done properly, on a hard task: sorting tens of thousands of posts into seven mental-health categories.
How
I designed a model that reads a post with a language model, lets it attend to the parts that matter, and then reads the sequence in both directions before deciding. Then I built two simpler models to compete with it and compared all three on the same held-out data, including a map of exactly where the custom model fails.
What came out
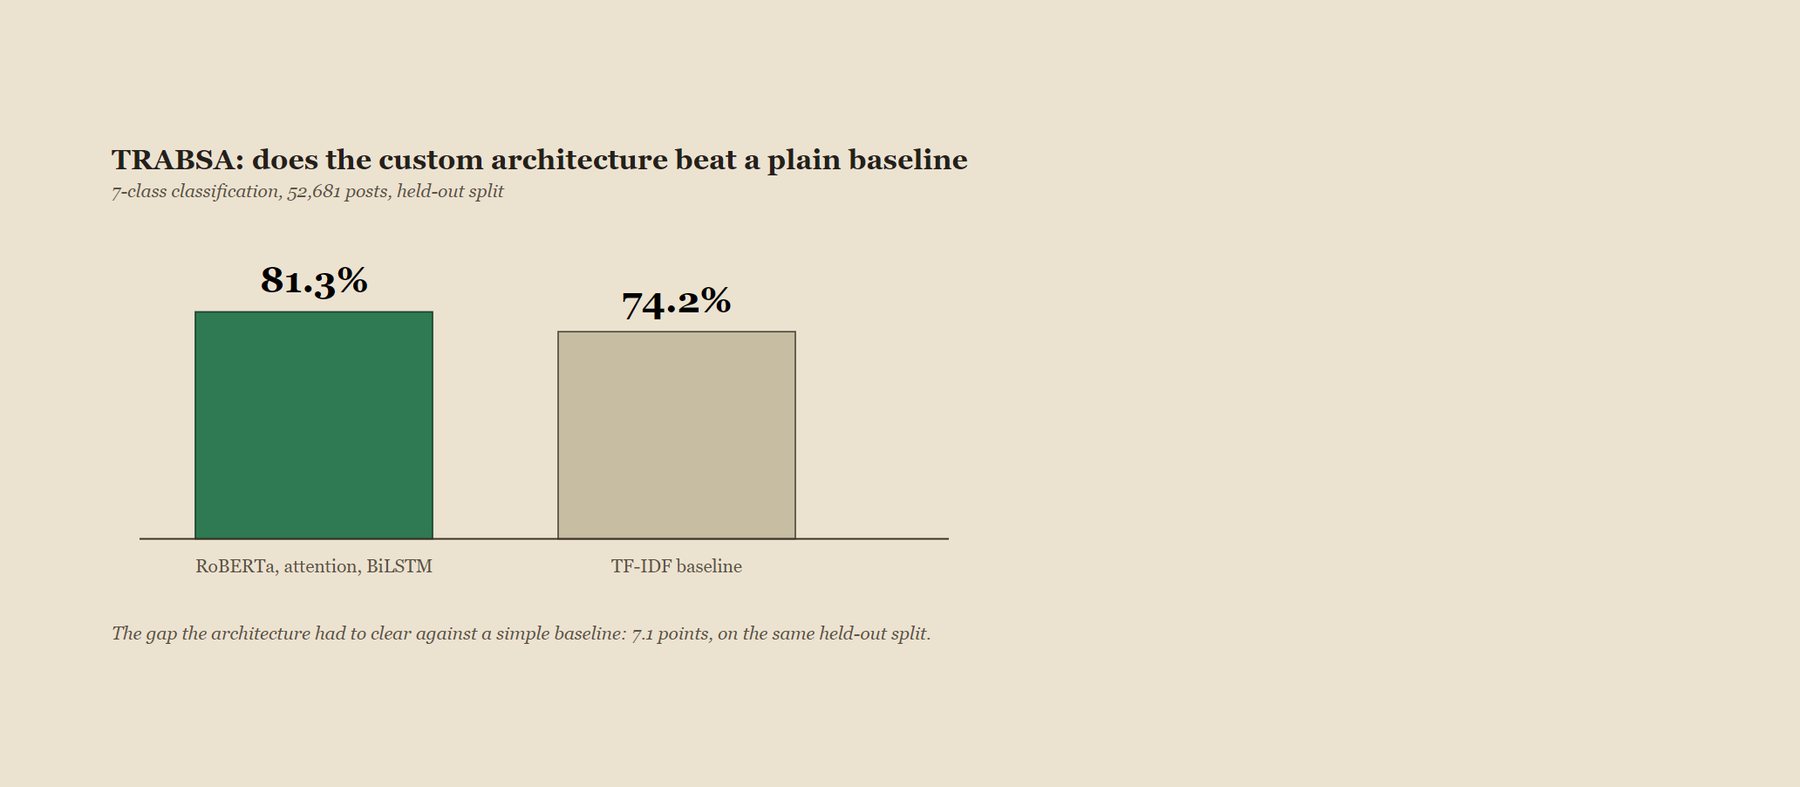
81.3%, accuracy, against 74.2% for the simple baseline it had to beat.
What broke
Two of the seven categories overlap so much in how people actually write that no model in the comparison could tell them apart. The confusion sits in the same two cells for every model, which says the label boundary is the problem, not the architecture.
Mind the gap
A group project. The code lives with a classmate, so there is no public repository for this station.