Quiet Neurons
Why
Pathway published a new kind of neural network, the Dragon Hatchling, with a claim about it: fewer of its neurons fire when the next piece of text is easy to guess. DataForge asked teams to explain one idea from that research to someone new to it. I wanted one claim, tested properly, on a real model you can poke yourself, not an animation of one.
How
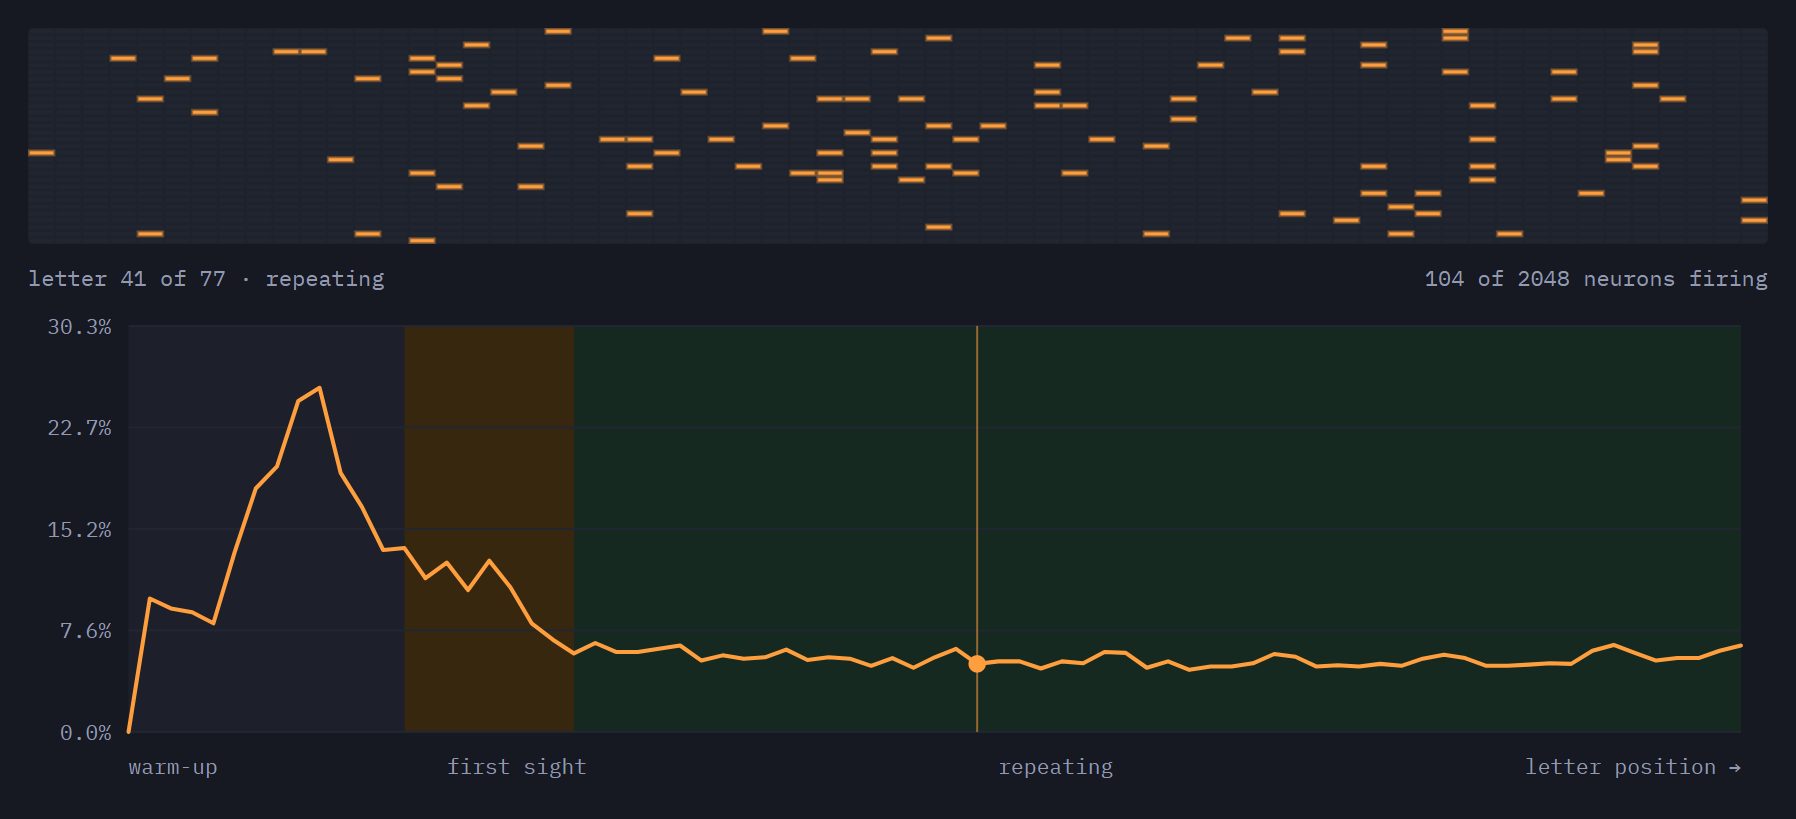
I trained small versions of the model at three sizes on the paper's own test task and checked the paper's claim first. It held. Then I found a case it does not cover: two stretches of text the model predicts equally well, where one uses far more neurons than the other. The difference is where the knowledge came from. Text memorised during training keeps neurons busy; text picked up a moment ago from the passage in front of it goes quiet. The page runs the real model in your browser, so you can change the word, inject a surprise, and watch the neurons answer.
What came out
A live explainer that opens without sign-in, runs the actual model rather than a recording, and teaches a sharper version of the claim than the paper states. An ordinary Transformer trained the same way shows no such effect, so on that comparison it belongs to this architecture rather than to the task.
What broke
I set out to prove something bigger: that surprise and quietness move together letter by letter. The data refused it, so the claim got narrower. I also said publicly that the effect grows steadily with model size; a second training run showed that two runs of the same size differ by more than the sizes do, so I took that back in the README. An accessibility check I had published was wrong too, and the most important button on the page failed the contrast standard I said it passed; it was fixed and measured again. What the page still cannot tell you is why memorised text needs more neurons.